Know what’s on your site before a plaintiff’s firm does
A free privacy audit shows which cookies, pixels and trackers are running — and which ones commonly appear in privacy claims.
Most discussions about cookie consent focus on scripts.
Block Google Analytics. Block Meta Pixel. Block advertising tags. Wait for the visitor to consent. Then release the appropriate technologies.
That sounds straightforward. It is also incomplete.
A browser can transmit data to a third party without executing a conventional <script> tag and without setting a cookie first. An ordinary-looking image request can initiate an HTTP connection to an outside server. A transparent tracking pixel can communicate information about the visitor. An iframe can load third-party content. CSS can retrieve a remote resource. JavaScript can instantiate an Image object without placing a visible image on the page. A site can transmit information through fetch(), XMLHttpRequest, navigator.sendBeacon() or server-side APIs.
Your Cookie Banner May Be Blocking Scripts and Still Leaking Data: The Technical Problem of Tracking Pixels, Image Requests and Pre-Consent Data Collection
That means a consent management platform that says it “blocks scripts before consent” may still allow network traffic that deserves exactly the same privacy scrutiny.
The Interactive Advertising Bureau’s own technical specifications recognize this problem. IAB Tech Lab describes advertising creatives containing pixels implemented through <img> elements and explains that an image URL triggers an HTTP GET request to the vendor even though the element cannot execute JavaScript. Its Transparency and Consent Framework contains specific mechanisms for passing consent information through URL-based services for precisely this reason.
This is not an obscure edge case.
It gets to the central technical question behind modern consent management:
Before a visitor has given the required consent, what information is actually leaving the browser?
A banner is an interface. Compliance depends on what happens underneath it.
An “image-based script” usually is not a script
The phrase “image-based script” sometimes gets used informally to describe tracking pixels. Technically, that terminology is misleading.
Consider this HTML:
<img
  src="https://tracker.example.com/pixel?event=pageview"
  width="1"
  height="1"
  alt=""
>
There is no JavaScript there.
The browser encounters the src attribute and makes a network request to tracker.example.com.
The server can respond with an image that is one pixel wide, a transparent GIF, a tiny PNG, or another resource. The visual response is largely irrelevant. The useful part for the tracker is frequently the request itself.
Depending on the implementation, that request can expose or contain information such as:
- the visitor’s IP address;
- browser and device information contained in HTTP headers;
- the requesting page or referrer;
- campaign identifiers;
- advertising identifiers;
- values encoded directly into the request URL;
- identifiers already stored by the destination domain;
- event names such as
Purchase,Lead,SignuporPageView; - product IDs or page categories;
- account, session or pseudonymous user identifiers;
- timestamp and request metadata.
IAB Tech Lab explicitly notes that information beyond the consent string can accompany these requests, including IP addresses and cookies associated with the receiving service.
The tracking mechanism therefore does not have to “drop a cookie” to create a privacy issue.
The browser has already communicated with another server.
That distinction is increasingly important.
Image-Based Scripts Explained: How Tracking Pixels Can Leak Data Before Consent
Privacy programs historically became overly focused on cookies because cookies were the most visible persistence mechanism.
Cookies remain important. But modern privacy engineering needs to think in terms of network transmissions, not merely cookie placement.
Suppose a website does this before consent:
<img src="https://analytics.example.com/p.gif?page=/cancer-treatment">The website may never set a cookie.
Yet the analytics provider has received a network request associated with:
- the visitor’s IP address;
- browser information;
- the
/cancer-treatmentcontext encoded in the URL; - potentially the referring page;
- potentially identifiers already associated with the vendor.
Whether that particular combination constitutes regulated personal information, protected health information or the contents of a communication depends on the applicable law and facts.
But technically, something has already been disclosed.
Deleting a cookie afterward cannot undo that transmission.
Neither can showing a consent banner five milliseconds later.
The Hidden Privacy Risk of Image-Based Scripts, Pixels, and Pre-Consent Tracking
This is one reason the IAB Transparency and Consent Framework does not treat consent as something relevant only to JavaScript APIs. IAB’s specifications effectively acknowledge the problem. IAB Tech Lab’s TCF documentation specifically addresses what it calls a “URL-based service” that cannot execute JavaScript.
Its example is straightforward: an advertising creative contains pixels under <img> tags. Loading one causes the browser to make an HTTP GET request to the vendor’s domain. Because the image element itself cannot query the CMP’s JavaScript API, IAB created URL macros that can carry the appropriate TC String to the vendor.
That is technically significant.
The ecosystem itself recognizes that a privacy-relevant advertising transaction can occur through an image URL.
If your consent architecture monitors only executable scripts, you are monitoring the wrong abstraction.
Why this matters more now
Tracking technology has become a recurring subject in privacy litigation.
Claims involving Meta Pixel, Google Analytics, session replay systems and similar technology have been brought under statutes including the California Invasion of Privacy Act, the federal Electronic Communications Privacy Act, the Video Privacy Protection Act and various state privacy and consumer-protection laws.
The viability of particular claims varies considerably by statute, jurisdiction, facts and procedural posture. Courts have dismissed some theories and allowed others to proceed. It would be incorrect to say that merely having a tracking pixel automatically violates CIPA or another privacy statute.
But it would be equally incorrect to dismiss the technical issue.
For example, in August 2026, the California Court of Appeal addressed a proposed class action against Adventist Health involving allegations that Meta Pixel and Google Analytics collected information from healthcare websites and transmitted information to Meta and Google.
The Third Circuit addressed another healthcare tracking case in August 2026 involving allegations that Meta Pixel captured IP addresses, device identifiers and users’ interactions with a health system’s website.
And in In re Meta Android Privacy Litigation, a federal district court described allegations concerning Meta’s tracking technology and the transmission of page URLs, searches, page activity and form information to Meta.
There are important legal differences among those cases. The technical lesson is simpler:
Courts and plaintiffs’ lawyers increasingly examine what information actually traveled between the user’s browser, the website and third parties.
That makes the network layer evidence.
Image-Based Tracking Scripts: What They Are, Why They Matter, and How to Block Them? CIPA makes the economics particularly uncomfortable
California’s Invasion of Privacy Act has attracted significant attention because of its private right of action and statutory damages provision.
California Penal Code § 637.2 provides for the greater of $5,000 per violation or three times actual damages for a qualifying violation of the chapter. The statute also states that actual damages are not necessarily a prerequisite to an action.
That does not mean every pixel transmission creates a $5,000 claim. Whether conduct falls within a particular CIPA provision is heavily disputed, and defenses concerning consent, party status, timing, interception, contents and other statutory requirements can matter enormously.
But it explains why seemingly minor website architecture has become litigation material.
An engineering team may see:
GET /pixel.gif
A complaint may characterize the same transaction as:
simultaneous transmission of a user’s electronic communication to an undisclosed third party before the user consented.
The technical facts matter.
Healthcare provides an especially clear example
The Department of Health and Human Services has specifically addressed online tracking technologies used by HIPAA-regulated organizations.
HHS identifies web beacons or tracking pixels, cookies, session replay and fingerprinting among technologies commonly used to collect information about website visitors. It also warns that third-party tracking technologies can send information directly to outside vendors.
There is important nuance here. A federal court vacated a portion of HHS’s earlier guidance concerning the combination of an IP address and a visit to certain unauthenticated health-related pages, and HHS acknowledges that ruling in its current guidance.
Still, the underlying engineering problem remains unchanged.
If a health system’s appointment page transmits patient-related information to an advertising vendor, the organization needs to know that it is happening.
A privacy policy saying “we use cookies” is not a packet filter.
Why conventional script blocking can fail
Here is where the problem becomes more technical.
A basic CMP implementation might search a page for something like:
<script src="https://thirdparty.example.com/tracker.js"></script>The CMP prevents that script from loading until the visitor accepts the relevant category.
That is useful.
But now consider:
<img src="https://thirdparty.example.com/pixel?id=12345">There is no script tag to block.
Or:
<iframe src="https://thirdparty.example.com/widget"></iframe>Again, no conventional tracking script is required to initiate the network request.
Or:
const pixel = new Image();
pixel.src =
  "https://thirdparty.example.com/collect?event=checkout";
The browser initiates an image request even though the image may never appear in the DOM.
Or:
navigator.sendBeacon(
  "https://thirdparty.example.com/collect",
  JSON.stringify(data)
);
The Beacon API exists specifically to send asynchronous information to a server and is commonly useful for analytics and end-of-session telemetry.
Or:
fetch("https://thirdparty.example.com/event", {
  method: "POST",
  body: JSON.stringify(data)
});
Or:
const xhr = new XMLHttpRequest();
xhr.open("POST", "https://thirdparty.example.com/event");
xhr.send(data);
A robust CMP needs to understand the difference between blocking a particular HTML element and controlling the broader collection and transmission architecture. It’s also important to understand why blocking JavaScript Is not enough as plaintiffs firms have taken a liking to image-based scripts and tracking pixel litigation. Even the vexatious litigant Vivek Shah didn’t know about this but he did exploit the search bar privacy lawsuits.
Technical Guide: How to Prevent Tracking Pixels and Other Requests Before Consent
There is no single browser API that magically solves every case.
The safest design uses multiple enforcement layers.
1. Begin with an explicit default-deny state
For jurisdictions or processing activities where affirmative consent is required, the site’s initial state should be:
Advertising: denied
Analytics: denied
Personalization: denied
Necessary: permitted
Nothing requiring one of the denied purposes should be allowed to execute merely because the CMP has not finished loading.
This is a critical architectural distinction.
Bad architecture:
Page loads
↓
Trackers load
↓
CMP loads
↓
CMP discovers no consent
↓
CMP attempts to disable trackers
By that point, the disclosure has already occurred.
Better architecture:
Initial consent state = denied
↓
Enforcement layer initializes
↓
Page resources are evaluated
↓
Only permitted resources load
↓
Visitor makes choice
↓
Consent state changes
↓
Eligible resources are released
Google makes essentially the same distinction in its documentation for Basic Consent Mode. In Google’s basic implementation, Google tags are blocked until the visitor interacts with the consent mechanism; Google says no data is transmitted to Google before consent under that configuration.
Advanced Consent Mode behaves differently and can transmit cookieless pings while consent is denied. That may be appropriate for some deployments, but organizations should understand the distinction rather than assuming “Consent Mode enabled” means “nothing is transmitted.”
2. Do not ship prohibited pixels in immediately executable HTML
This is one of the most reliable controls.
Instead of:
<img
  src="https://tracker.example.com/pixel?event=view"
  width="1"
  height="1"
>
render something like:
<img
  data-consent-src="https://tracker.example.com/pixel?event=view"
  data-consent-category="advertising"
  width="1"
  height="1"
  alt=""
>
There is no src.
Therefore the browser has nothing to request.
After advertising consent is established:
document
  .querySelectorAll(
    'img[data-consent-category="advertising"][data-consent-src]'
  )
  .forEach((img) => {
    img.src = img.dataset.consentSrc;
  });
The important concept is not this particular code.
It is that the actual network-producing attribute does not exist until permission exists.
This technique can be extended to:
iframe[src]
video[src]
audio[src]
source[src]
link[href]
img[srcset]
source[srcset]
depending on what the site uses and what needs consent.
3. Account for srcset, not just src
Modern images often use responsive sources:
<img
  src="default.jpg"
  srcset="
    tracker.example.com/a.jpg 1x,
    tracker.example.com/b.jpg 2x
  "
>
A blocking system that inspects only src can miss the network calls triggered from srcset.
Consent tooling should therefore inspect both.
The same concept applies to <source> elements inside <picture>.
4. Detect dynamically created Image objects
This pattern is common:
const img = new Image();
img.src = trackingUrl;
A DOM scanner alone may never see the request in time.
The browser can begin retrieving the resource as soon as the src property is assigned.
A CMP that intends to enforce policy at runtime may therefore need to control assignments to image sources or, preferably, prevent the upstream third-party code responsible for creating the image from executing at all.
That second approach is usually safer.
If tracker.js is the code that generates ten different pixels, block tracker.js until consent rather than trying to chase every pixel it creates afterward.
But runtime request interception still provides useful defense in depth.
5. Do not rely exclusively on MutationObserver
A sophisticated CMP will often use MutationObserver to detect elements injected into the DOM.
For example:
const observer = new MutationObserver((mutations) => {
  // examine newly inserted elements
});
This is useful for dynamically injected tags.
But it should not be the only control.
By the time a MutationObserver callback sees:
<img src="https://tracker.example.com/pixel">the browser may already have initiated the request.
The same race condition can occur when third-party JavaScript creates a node, assigns src, and then appends it.
The correct engineering objective is therefore:
prevent the request from becoming eligible to start, rather than merely remove the element after discovering it.
6. Handle iframes separately
An iframe is effectively another browsing context:
<iframe src="https://thirdparty.example.com/widget"></iframe>Its contents can perform their own tracking.
A common privacy-preserving pattern is:
<iframe
  data-consent-src="https://thirdparty.example.com/widget"
  data-consent-category="marketing"
></iframe>
The CMP assigns the real src only after the corresponding consent exists.
For embedded video, maps, chat widgets and social-media embeds, the pre-consent experience can instead display a placeholder:
This content is provided by a third party.
Enable Marketing Content to load it.
The important point is that the third-party iframe should not already exist behind the placeholder.
If it has loaded, the placeholder is cosmetic.
7. Pay special attention to <noscript> pixels
Advertising tags frequently ship with a JavaScript component plus fallback markup such as:
<noscript>
  <img
    src="https://tracker.example.com/pixel"
    width="1"
    height="1"
  >
</noscript>
This deserves special attention because a JavaScript-based CMP cannot control the page when JavaScript is disabled.
If the browser renders the <noscript> content and the tracking URL is present, the pixel may fire without the CMP ever executing.
Possible mitigations include:
- removing unnecessary tracking fallbacks;
- generating them server-side only when a valid consent state already exists;
- using server-side HTML transformation;
- restricting destinations through Content Security Policy where appropriate.
Simply inserting a JavaScript consent banner does not solve a <noscript> tracking problem.
8. Inspect CSS-triggered resources
CSS can initiate network calls as well.
For example:
.tracking-marker {
  background-image:
    url("https://tracker.example.com/pixel?id=123");
}
A browser that renders the relevant style may retrieve that resource.
Other CSS constructs and externally hosted assets can create similar network activity.
This is one reason scanner technology should inventory network destinations rather than assume that every privacy-relevant call originates from <script>.
9. Inspect resource hints
Sites can tell browsers to make connections early:
<link
  rel="preconnect"
  href="https://tracker.example.com"
>
or retrieve resources early through mechanisms such as preload or prefetch.
A privacy implementation should inspect:
preconnect
dns-prefetch
prefetch
preload
modulepreload
A preconnect does not necessarily transmit the same event information as a tracking pixel, but it can still cause an early connection to a third-party infrastructure provider.
More importantly, prefetching or preloading a prohibited resource can defeat the intent of delaying that resource until consent.
10. Gate fetch()
Blocking image requests is only part of the problem.
Modern analytics libraries frequently use the Fetch API:
fetch("https://analytics.example.com/event", {
  method: "POST",
  headers: {
    "Content-Type": "application/json"
  },
  body: JSON.stringify(event)
});
Where appropriate, consent enforcement should prevent nonessential destinations or events from being called until authorization exists.
Usually the cleanest solution is to prevent the analytics library itself from initializing.
Runtime interception of fetch() can serve as an additional protection against unknown or dynamically created traffic.
11. Gate XMLHttpRequest
Legacy and current libraries may still use XHR:
const xhr = new XMLHttpRequest();
xhr.open(
  "POST",
  "https://analytics.example.com/collect"
);
xhr.send(payload);
Consent enforcement should include the same policy decision:
Is destination allowed?
Is purpose allowed?
Has required consent been obtained?
If not:
do not send.12. Gate navigator.sendBeacon()
Beacon deserves particular attention because analytics systems often use it exactly when a user is leaving a page.
MDN describes navigator.sendBeacon() as a mechanism for asynchronously sending a small HTTP POST request and notes its analytics use case.
That makes it an obvious area for consent enforcement.
A browser session could otherwise behave perfectly during most of the page visit and transmit analytics information upon pagehide or unload.
Your testing should include navigation away from the page.
13. Do not forget server-side tagging
This may be the most important blind spot in newer implementations.
Suppose the browser sends:
Browser
  ↓
firstparty.example.com/events
  ↓
company server
  ↓
Meta
  ↓
Google
  ↓
advertising platforms
A scanner observing only obvious third-party browser calls might see traffic going to the company’s own domain.
But the server then forwards the data elsewhere.
Google’s own documentation recognizes that Consent Mode can operate with server-side Tag Manager and requires consent information to flow through the web container into the server-side environment where tags are processed.
Therefore:
client-side consent must follow the event downstream.
A server-side pipeline should not operate as:
Receive event
↓
Forward everywhere
It should operate more like:
Receive event
↓
Read consent state
↓
Determine permitted purposes/vendors
↓
Forward only authorized event destinations
↓
Record enforcement decision
Moving tracking from the browser to the server does not make the underlying privacy question disappear.
14. Treat Meta Conversions API and similar systems separately
The same applies to server-to-server conversion APIs.
A company might correctly block Meta Pixel in the browser and then send substantially similar event information to Meta through a server-side integration.
From a consent and privacy standpoint, that can defeat the entire purpose of client-side blocking.
Consent architecture must cover:
browser pixels
+
browser scripts
+
server-side event forwarding
+
conversion APIs
+
CRM integrations
+
advertising APIs
The system needs a common source of truth regarding the visitor’s privacy choices.
15. Use Content Security Policy as defense in depth
Content Security Policy can restrict the destinations from which different resource types may load.
For example:
Content-Security-Policy:
  default-src 'self';
  img-src 'self' data:;
  frame-src 'self';
  connect-src 'self';
That would prevent many third-party image, frame and network destinations unless explicitly allowed.
Real production CSP rules are usually more complex.
CSP also is not, by itself, an ideal substitute for a CMP because user consent can change during a session and a response-header CSP is not designed to function as a complete dynamic consent engine.
But it is powerful defense in depth.
If the privacy layer fails and an unknown advertising pixel attempts to call an unauthorized domain, CSP can provide another barrier.
For organizations dealing with especially sensitive information, that is worth considering.
The Hardest Problem: The Browser Can Beat a Cheap CMP
There is another subtle issue.
Browsers optimize aggressively.
While parsing HTML, the browser may discover resources and begin loading them before ordinary page JavaScript has completed execution.
That means this architecture can be dangerous:
<head>

  <script src="/cmp.js"></script>

  ...

</head>

<body>

  <img src="https://tracker.example.com/pixel">

</body>
A developer may assume:
The CMP is first, therefore it will block the image.
That assumption needs to be tested rather than trusted.
Browsers use mechanisms such as speculative parsing and preload scanning to discover resources rapidly.
The more reliable solution is not to give the browser an executable tracking URL in the first place.
Instead of:
<img src="TRACKING_URL">deliver:
<img data-consent-src="TRACKING_URL">Or omit the element entirely until consent exists.
This is why server-side HTML transformation can be valuable.
The server can ensure the forbidden resource does not exist in actionable form when the document first arrives.
A Better CMP Architecture
An advanced consent engine should think in terms of a policy enforcement pipeline.
Conceptually:
RESOURCE DISCOVERED
        ↓
IDENTIFY RESOURCE TYPE
        ↓
IDENTIFY DESTINATION
        ↓
CLASSIFY VENDOR
        ↓
CLASSIFY PURPOSE
        ↓
READ REGION
        ↓
READ USER CONSENT
        ↓
APPLY POLICY
      ↙     ↘
   ALLOW    BLOCK
              ↓
          HOLD RESOURCE
              ↓
        CONSENT CHANGES?
              ↓
            ALLOW
This is more robust than maintaining a simple list of scripts.
The classification engine should understand at least:
SCRIPT
IMAGE / PIXEL
IFRAME
FETCH
XHR
BEACON
CSS RESOURCE
VIDEO
AUDIO
RESOURCE HINT
SERVER-SIDE EVENT
It should also associate resources with vendors and purposes.
For example:
graph.facebook.com
Vendor: Meta
Purpose: Advertising / Measurement

google-analytics.com
Vendor: Google
Purpose: Analytics

doubleclick.net
Vendor: Google
Purpose: Advertising
The actual production taxonomy will be much larger and must account for customer-specific endpoints and first-party proxies.
Domain Blocking Alone Is Not Enough
Another tempting solution is simply:
Block facebook.com
Block doubleclick.net
Block analytics vendors
That is useful but incomplete.
Modern implementations may use:
- custom domains;
- CNAME records;
- first-party collectors;
- reverse proxies;
- server-side tag managers;
- CDN endpoints;
- customer-specific collection URLs.
For example:
metrics.customer.commay appear first-party while forwarding events into a third-party analytics system.
A modern scanner therefore benefits from looking beyond hostname alone.
Useful signals can include:
URL patterns
request payloads
response headers
JavaScript signatures
redirect chains
DNS/CNAME relationships
known vendor endpoints
event parameter names
initiator stack
destination IP/network
The objective is classification by behavior, not merely by name.
This Is Where Continuous Scanning Becomes Important
A one-time cookie audit cannot reliably solve this problem.
Websites change constantly.
Marketing deploys a new campaign.
An agency adds a tag.
Google Tag Manager receives a new container version.
A chat vendor changes infrastructure.
A new advertising pixel appears.
A developer changes an iframe.
A server-side analytics endpoint is introduced.
An A/B testing platform injects additional technology.
The site that was compliant on Monday may transmit a new third-party request on Thursday.
For that reason, privacy monitoring increasingly needs to behave more like security monitoring:
scan
↓
classify
↓
detect
↓
compare
↓
alert
↓
block/remediate
↓
preserve evidence
A cookie inventory tells you what was found.
Continuous network monitoring tells you what the website is actually doing.
That is a materially different control.
Testing Whether Your CMP Actually Blocks Tracking Pixels
A compliance team should be able to prove this and only a few CMPs are considered Gold standard to respect users consent choices and Captain Compliance’s consent management solution is one of those.
Do not merely look at the banner.
Open the browser’s Developer Tools.
Select:
NetworkClear existing traffic.
Open a fresh private/incognito session.
Before clicking the banner, inspect every request.
Filter by:
Img
Fetch/XHR
JS
Doc
Other
Then look for calls to:
Meta
Google
TikTok
LinkedIn
Microsoft
advertising exchanges
session replay providers
analytics vendors
marketing platforms
unknown domains
Repeat the test after clicking:
Reject AllThen repeat after:
Accept AllThen test custom preference combinations.
A properly functioning system should produce materially different network behavior depending on the consent state.
For example:
Before consent:
Necessary traffic only

Reject:
Necessary traffic only

Analytics only:
Necessary + authorized analytics

Marketing accepted:
Necessary + analytics + advertising
The test should also include:
page load
scroll
button clicks
form interaction
checkout
navigation
page exit
video play
search
login/logout
SPA route changes
Single-page applications deserve particular attention because navigation often occurs without a full browser reload.
Inspect the Initiator
Chrome and other browser developer tools can show what initiated a request.
That is extremely useful.
Suppose you find:
https://vendor.example.com/pixelThe initiator may reveal:
marketing.jsor:
gtm.jsor:
document parseror another application component.
That tells engineering where enforcement needs to happen.
If GTM caused the pixel, fix the trigger and consent configuration.
If the parser caused it, change the HTML.
If a third-party script dynamically created it, stop the script.
If a first-party API forwarded it server-side, fix the server.
Google Tag Manager Needs Consent Governance Too
Tag managers create another frequent misconception:
“Everything is in GTM, so the CMP controls it.”
Not necessarily.
GTM can contain tags whose trigger configuration ignores consent.
A proper deployment should map tag firing to consent requirements.
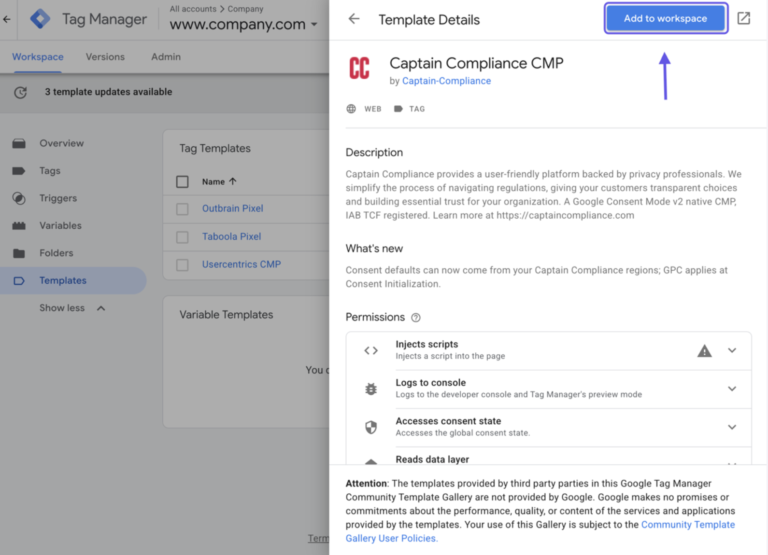
Google itself says organizations must ensure both Google tags and third-party tags behave according to the user’s consent decision. Tags that lack built-in consent checks can be given additional consent requirements inside Tag Manager.
The implementation should be tested empirically.
Do not conclude that a tag is controlled merely because someone checked a box in GTM.
Look at the network.
Consent Logging Matters Almost as Much as Blocking
When a privacy demand arrives months later, an organization may be asked:
What happened when this visitor arrived on the website?
That requires more than a screenshot of today’s banner.
Useful evidence can include:
timestamp
consent configuration version
region
banner version
purposes presented
vendors presented
initial consent state
visitor selection
consent-state changes
TC String / GPP signal where applicable
CMP version
tag configuration
scanner results
network test results
deployment history
The distinction between:
"We believe the pixel was blocked"and:
"Our logs show that advertising consent was denied at 14:32:11 UTC, Meta was categorized as Advertising, and its resources remained blocked throughout the session"can be substantial.
This is one reason consent logs should be designed as evidence rather than merely analytics.
A Privacy Policy Does Not Fix a Pre-Consent Transmission
Another common mistake is treating disclosure as a substitute for technical control.
A privacy policy can explain what an organization does.
It cannot retroactively prevent a browser from sending information.
The sequence matters.
Bad sequence:
User arrives
↓
Data goes to advertising vendor
↓
Banner appears
↓
User rejects
Better sequence:
User arrives
↓
Advertising transmission blocked
↓
Banner appears
↓
User chooses
↓
Transmission permitted only if authorized
The same principle applies when organizations rely on consent for a particular activity.
Consent obtained after the disclosure is not technically the same thing as consent obtained before the disclosure.
“Reject All” Has to Mean Something Technically
A button is not compliance.
If a visitor clicks Reject All but the website continues sending events to the same third parties, the user interface and technical behavior have diverged.
That creates several problems at once.
First, it undermines the consent mechanism.
Second, it can make representations in the banner or privacy notice inaccurate.
Third, it creates poor evidence if litigation or a regulator later examines what the system actually did.
A mature consent platform therefore needs automated verification:
Consent = Reject
Expected behavior = vendor blocked
Observed behavior = request attempted

RESULT: FAILURE
That is closer to a compliance control than simply rendering a banner.
What Captain Compliance Should Be Testing
For a platform such as Captain Compliance, the requirement should be broader than:
Block image scripts.
A technically meaningful requirement would be:
Captain Compliance should detect, classify and suppress consent-requiring network activity before the applicable consent exists, regardless of whether the activity originates through a script, tracking pixel, image request, iframe, beacon, Fetch request, XMLHttpRequest, tag manager, CSS resource or other browser mechanism.
The product should also account for server-side forwarding.
A useful engineering checklist would include:
[ ] script src
[ ] inline scripts that inject vendors
[ ] img src
[ ] img srcset
[ ] picture/source
[ ] dynamically instantiated Image()
[ ] iframe src
[ ] noscript pixels
[ ] CSS URLs
[ ] fetch()
[ ] XMLHttpRequest
[ ] navigator.sendBeacon()
[ ] preload
[ ] prefetch
[ ] preconnect
[ ] Google Tag Manager
[ ] Google Consent Mode
[ ] IAB TCF signals
[ ] GPP signals
[ ] SPA navigation
[ ] server-side GTM
[ ] conversion APIs
[ ] first-party proxy endpoints
Then continuously verify the result against the browser’s actual traffic.
The Standard Should Be “No Unauthorized Request Leaves”
This is ultimately the clearest engineering rule.
Do not ask:
Did we block cookies?
Do not ask only:
Did we block scripts?
Ask:
Before the applicable consent or other legal authorization existed, did the browser or our servers transmit data to a destination that should not have received it?
That framing catches much more.
It catches the transparent pixel.
It catches the iframe.
It catches the Image() request nobody saw.
It catches the beacon sent while the visitor closes the page.
It catches the Google Tag Manager tag someone added six months after the CMP implementation.
It catches the first-party endpoint forwarding data to a server-side advertising API.
And it forces the privacy program to evaluate the actual data flow instead of the appearance of the website.
The Larger Privacy Engineering Lesson
The privacy industry has spent years talking about cookie banners.
The actual compliance problem is considerably broader.
Modern websites are distributed software systems. They communicate with advertising platforms, analytics providers, CRMs, CDPs, video providers, chat systems, payment processors, experimentation platforms and dozens of other services.
Any of those connections can potentially create a disclosure.
Some use cookies.
Some use JavaScript.
Some use pixels.
Some use APIs.
Some operate server-side.
A serious consent management platform therefore cannot simply manage cookies.
It has to manage data transmission.
That requires a combination of:
- resource discovery;
- vendor classification;
- consent-state management;
- pre-execution blocking;
- network-level verification;
- continuous scanning;
- server-side enforcement;
- auditable logs.
The small transparent GIF that nobody notices is a good illustration of why.
To the visitor, nothing happened.
To the browser, an HTTP request occurred.
To the vendor, information may have arrived.
And to a plaintiff’s lawyer, regulator or forensic investigator looking at a network trace months later, that request may be the most important thing that happened on the page.
The safest approach is therefore straightforward:
Do not give a prohibited request an opportunity to leave the browser in the first place.
Then verify that it did not.
And retain the evidence showing why.
Put this into practice
Turn privacy guidance into working controls.
Captain Compliance helps teams discover tracking technologies, enforce consent, manage privacy requests and document the evidence behind every decision.